
MGni.py#
MGni.py (🔉IPA:’mæɡni-paɪ’ ) is a lightweight python client and toolkit for the MGnify API v2 .




Contents#
Features#
FAIR: More findable MGnify analyses and metadata, returned in familiar metagenomics data formats (e.g., GFF, Darwin Core , Dataframes [pandas , polars , anndata ])
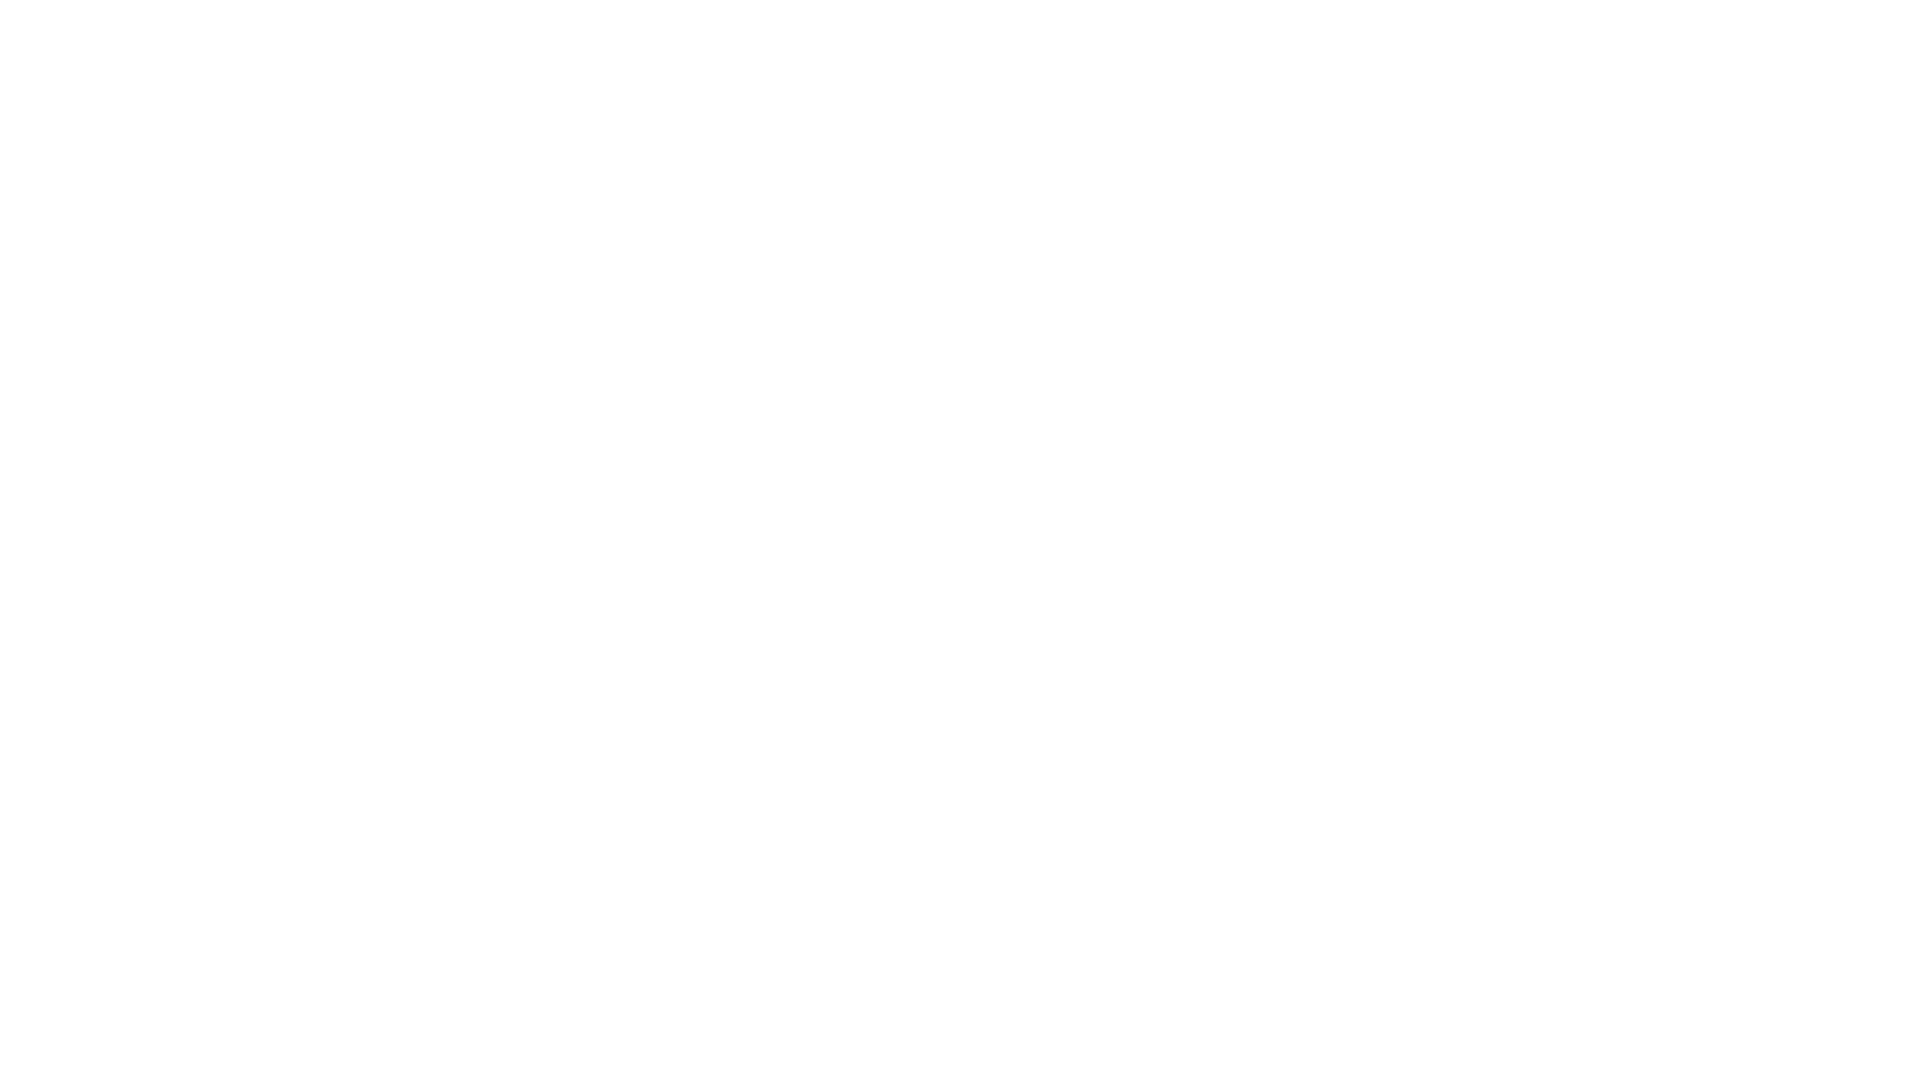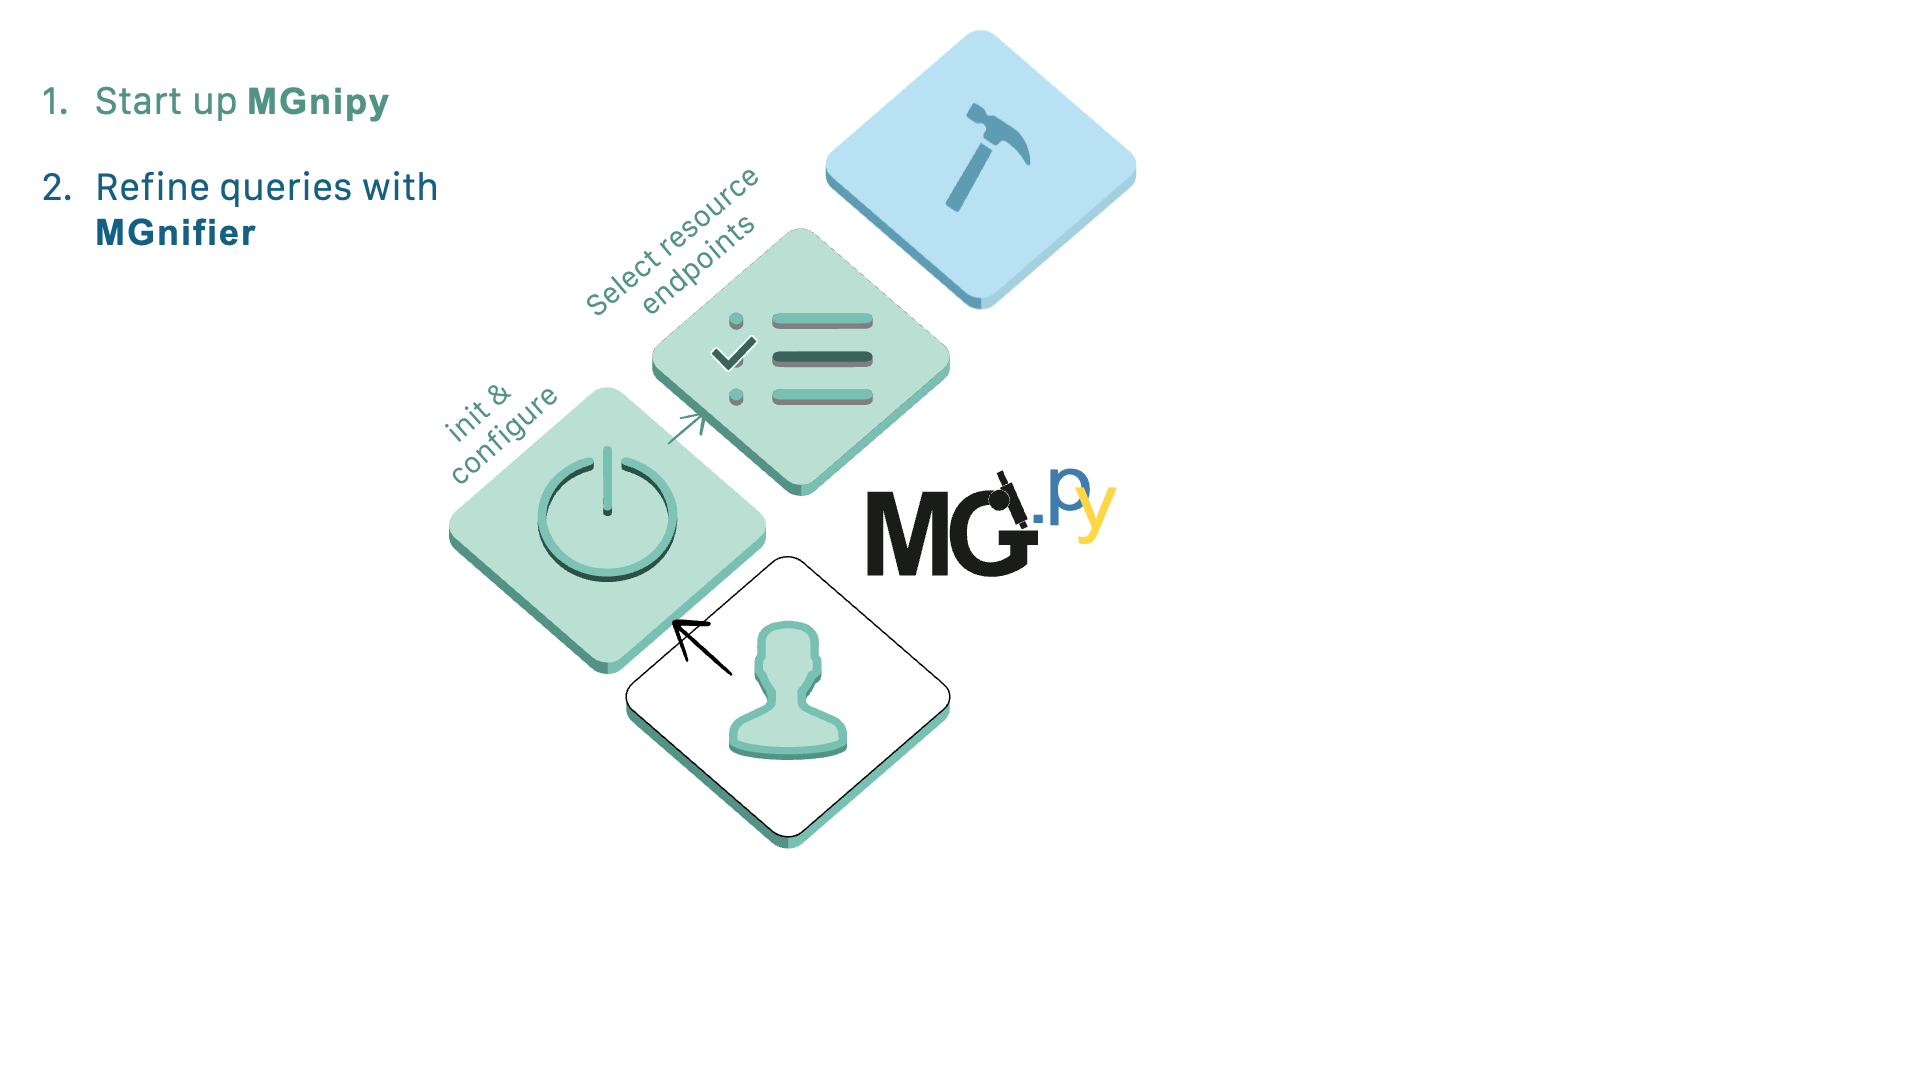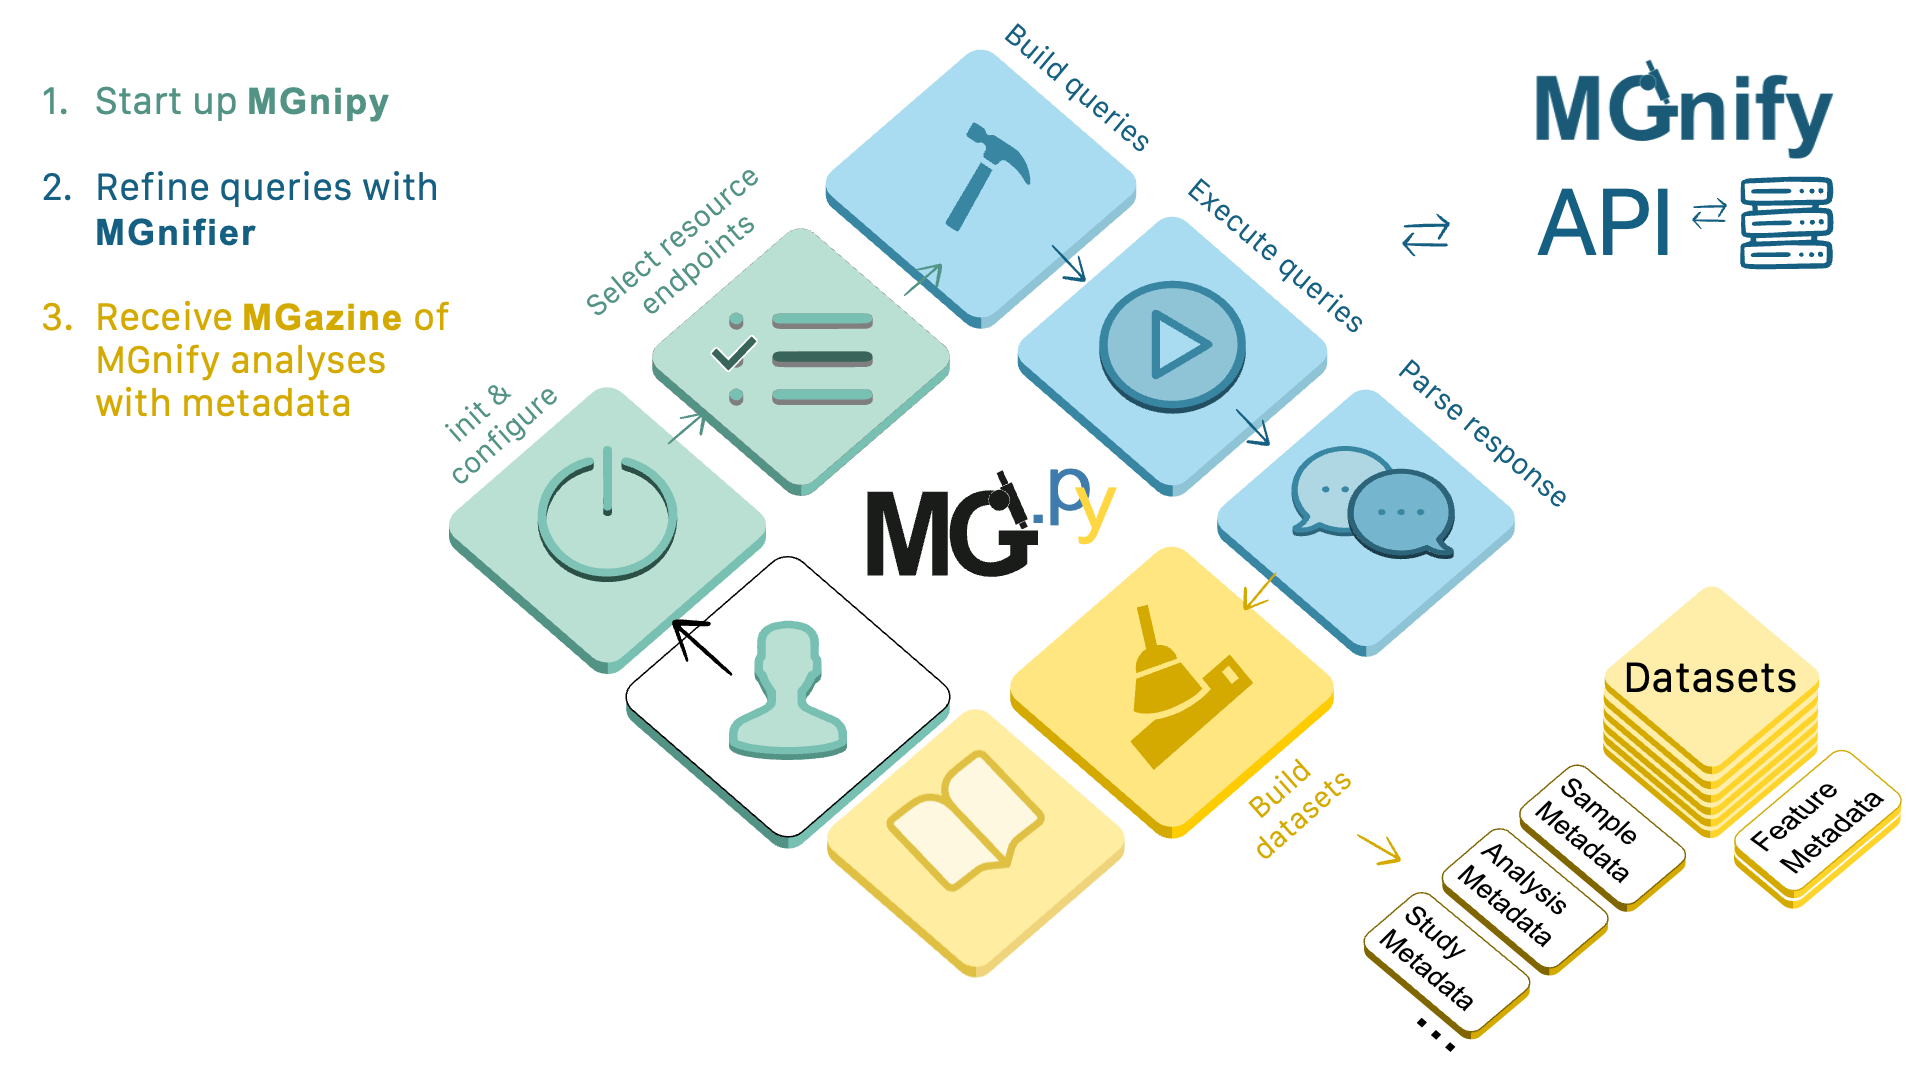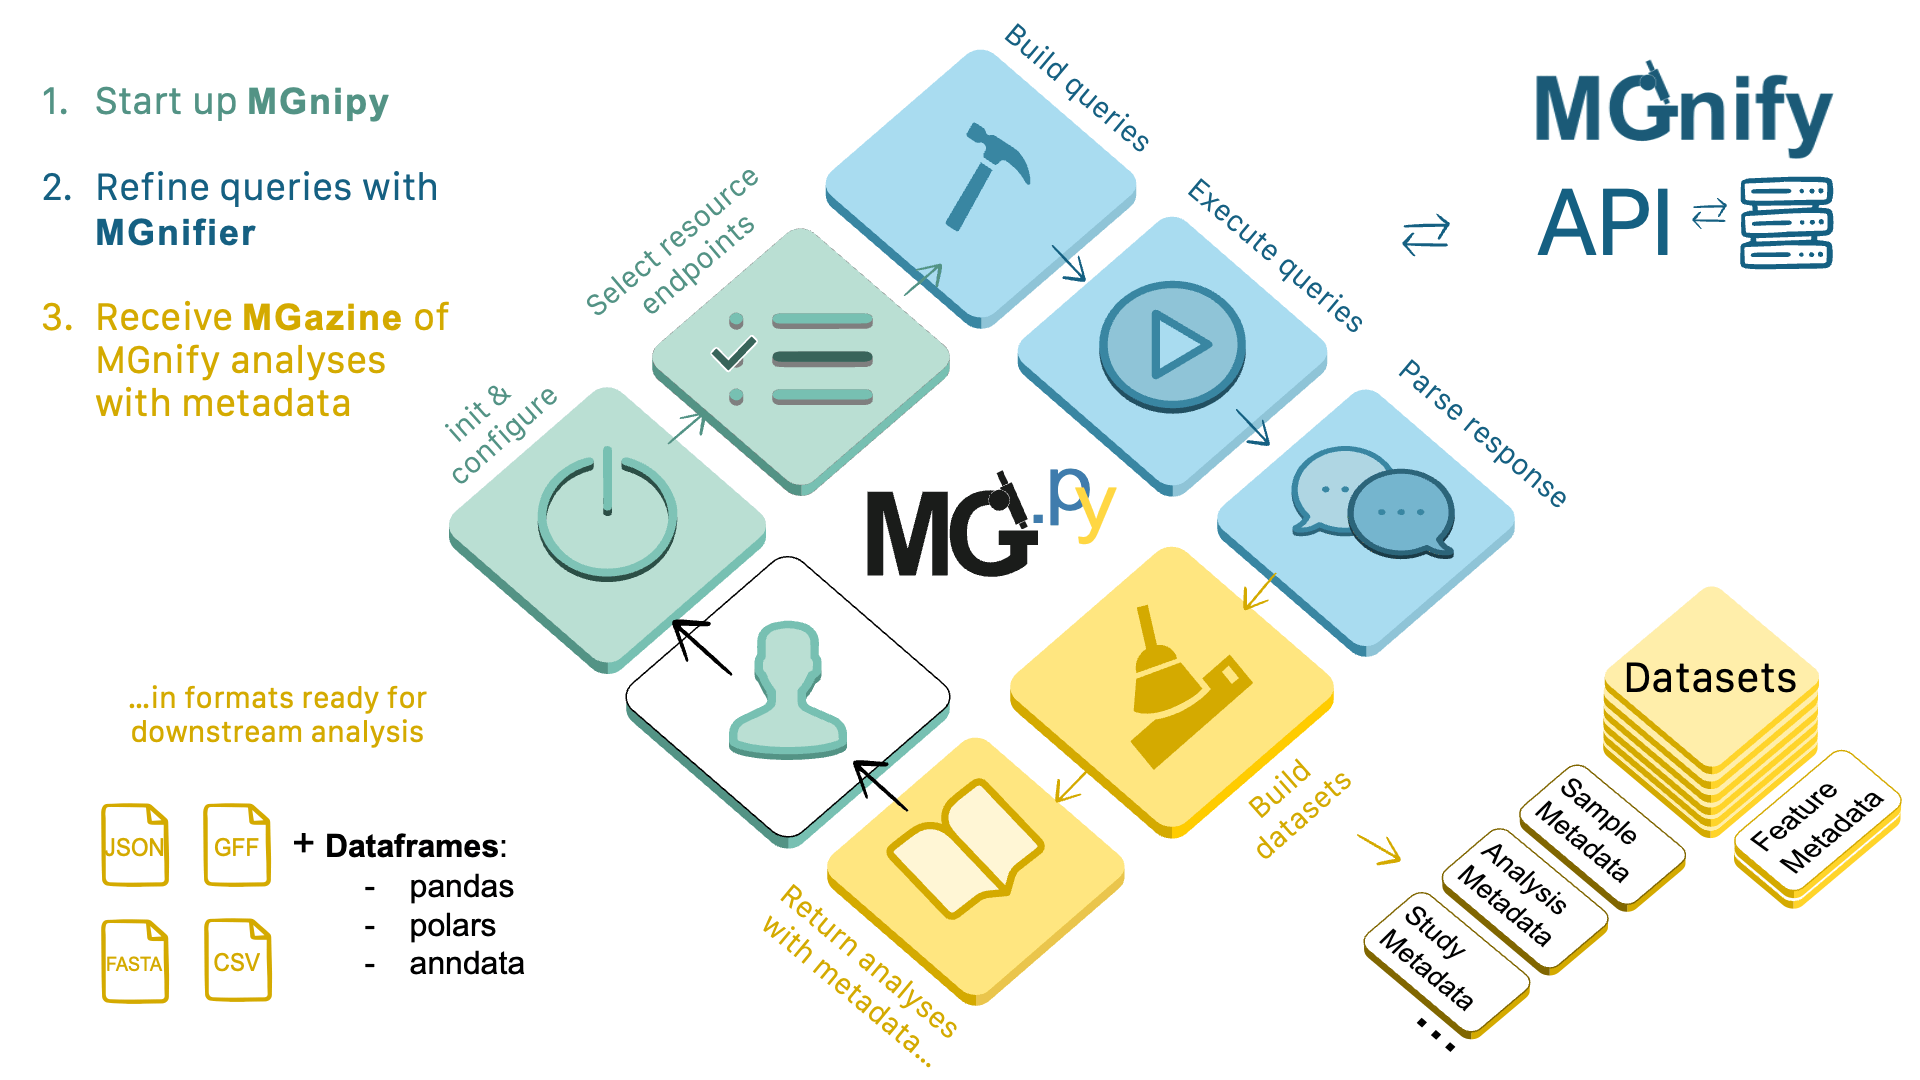
Simplifies API interactions: Let MGni.Py handle the complexity of building, executing, and parsing API calls so you can focus on the data!
Fast: MGni.Py uses caching to speed up API expolation, as well as supports both sync and async API calls
Supported MGnify API resources #
Note
Accessing your private data
To access your private data in any of these API endpoints you just need your MGnify user and password to obtain a valid sliding auth token via the MGnify Authentication endpoints .
for example you can put your login credentials in a
.envfile in your working directory (see .env.example ) andmgnipy.MGnipyConfigtakes care of getting and caching the auth token so that you can easily access your private data using MGni.py 🎉
Installation#
From PyPI#
pip install mgnipy
Development installation#
git clone https://github.com/EBI-Metagenomics/mgnipy.git
cd mgnipy
uv sync --all-groups  # or: pip install -e ".[dev,docs]"
Quick Start#
🚀 1. Initialize mgnipy.MGnipy#
from mgnipy import MGnipy

# Create the main client, with default configuration
mg = MGnipy()

# See available endpoints
mg.list_resources()
🔎 2. Search resources with a mgnipy.MGnifier#
Building the query set#
# Search for studies keyword
studies = mg.studies(
    search="disease"
)

# Can preview requests before fetching
studies.explain()
Executing the queries#
# client context manager
with MG:

    # get page by page via .get()
    studies.get()
    # or via .page(), getting a specific pg num
    studies.page(2)
    # OR potentially all at once in large batches (also async option .aget_all())
    studies.get_all()

    # then can enrich list with detailed metadata
    studies.enrich_details()
Viewing the search results#
# the mgnify list (without details)
study_list = studies.search_results
# detailed metadata, e.g. with enriched details
detailed_study_list = studies.metadata

# e.g. as dataframes
pl_metadata = detailed_study_metadata.to_polars()
pd_metadata = detailed_study_metadata.to_pandas()

# e.g. as json
json_metadata = detailed_study_metadata.to_json()
🗃️ 3. Explore a mgnipy.MGazine of datasets#
# accessing the mgazine of datasets
mgazine = studies.datasets

# preview
print(mgazine)
Downloading datasets from MGnify#
# download file by file
mgazine.download(
    alias="mgnify_file_alias.fasta.gz",
    to_dir="downloads_folder"
)

# or download all
mgazine.download_all(to_dir="downloads_folder")
Reading in datasets from MGnify#
# support for tsv, csv, txt, jsonl
taxa_table = mgazine.stream(
    alias="mgnify_file_alias.tsv",
    df_engine="polars"
)

# support for fasta, gff, biom via skbio
skbio_fasta = mgazine.stream(alias="mgnify_file_alias.fasta.gz")
Additional Documentation#
Development#
see Contributing.md
License#
This project is licensed under the GNU General Public License v3.0 or later (GPL-3.0-or-later). See the included LICENSE file for full terms.
Citation#
If you use MGni.py in your work, please cite the project:
MGnipy contributors (2026). MGni.py: a lightweight Python client and toolkit for the MGnify API. Version 0.2.1. https://github.com/EBI-Metagenomics/mgnipy
BibTeX:
@software{mgnipy2026,
  author = {MGnipy contributors},
  title = {MGni.py: a lightweight Python client and toolkit for the MGnify API},
  year = {2026},
  version = {0.2.1},
  url = {https://github.com/EBI-Metagenomics/mgnipy}
}
Important
Also cite MGnify when using MGnify data or analyses: https://docs.mgnify.org/src/docs/about.html#how-to-cite
Thank you#
A list of people who have contributed to this repository. Please add your name and github or email if you’d like.
From the Multiomics Network Analytics team @ Danmarks Tekniske Universitet (DTU):
Angel L. P. (angelphanth) - PhD student and visitor to Microbiome Informatics team
Maria Barranco - Postdoc
Sebastián Ayala Ruano (sayalaruano) - Previous MSc student and Research Assistant
Alberto Santos Delgado (albsantosdel) - Senior Researcher and BRIGHT Informatics Platform Director
From the Microbiome Informatics team @ The European Bioinformatics Institute (EMBL-EBI):
Mahfouz Shehu (MGS-sails) - Mgnify Website Developer
Christian Atallah (chrisAta) - Bioinformatician Mgnify
Sandy Rogers (SandyRogers) - MGnify Web and Platform Project Leader
Martin Beracochea (mberacochea) - MGnify Production Project Leader
Robert Finn (rdf [at] ebi.ac.uk ) - Section Head, Team Leader and Senior Scientist
Extra special thanks to:
Prof. Rob Finn and everyone in the Microbiome Informatics team and Finn Group at EMBL-EBI for their mentorship
My Prof. Alberto Santos for making this colab happen and also constant guidance and patience
The Danemo Stipend, Reinholdt W. Jorck og Hustrus Fond, and William Demant Fonden for their generous travel grants so that I could go to EBI
The Informatics Platform at BRIGHT at DTU for their mentorship
The creators of this
python_packagetemplate and especially Henry Webel (enryH)The creators and maintainers of openapi-python-client